
Spectral framework to measure diversity in MSAs
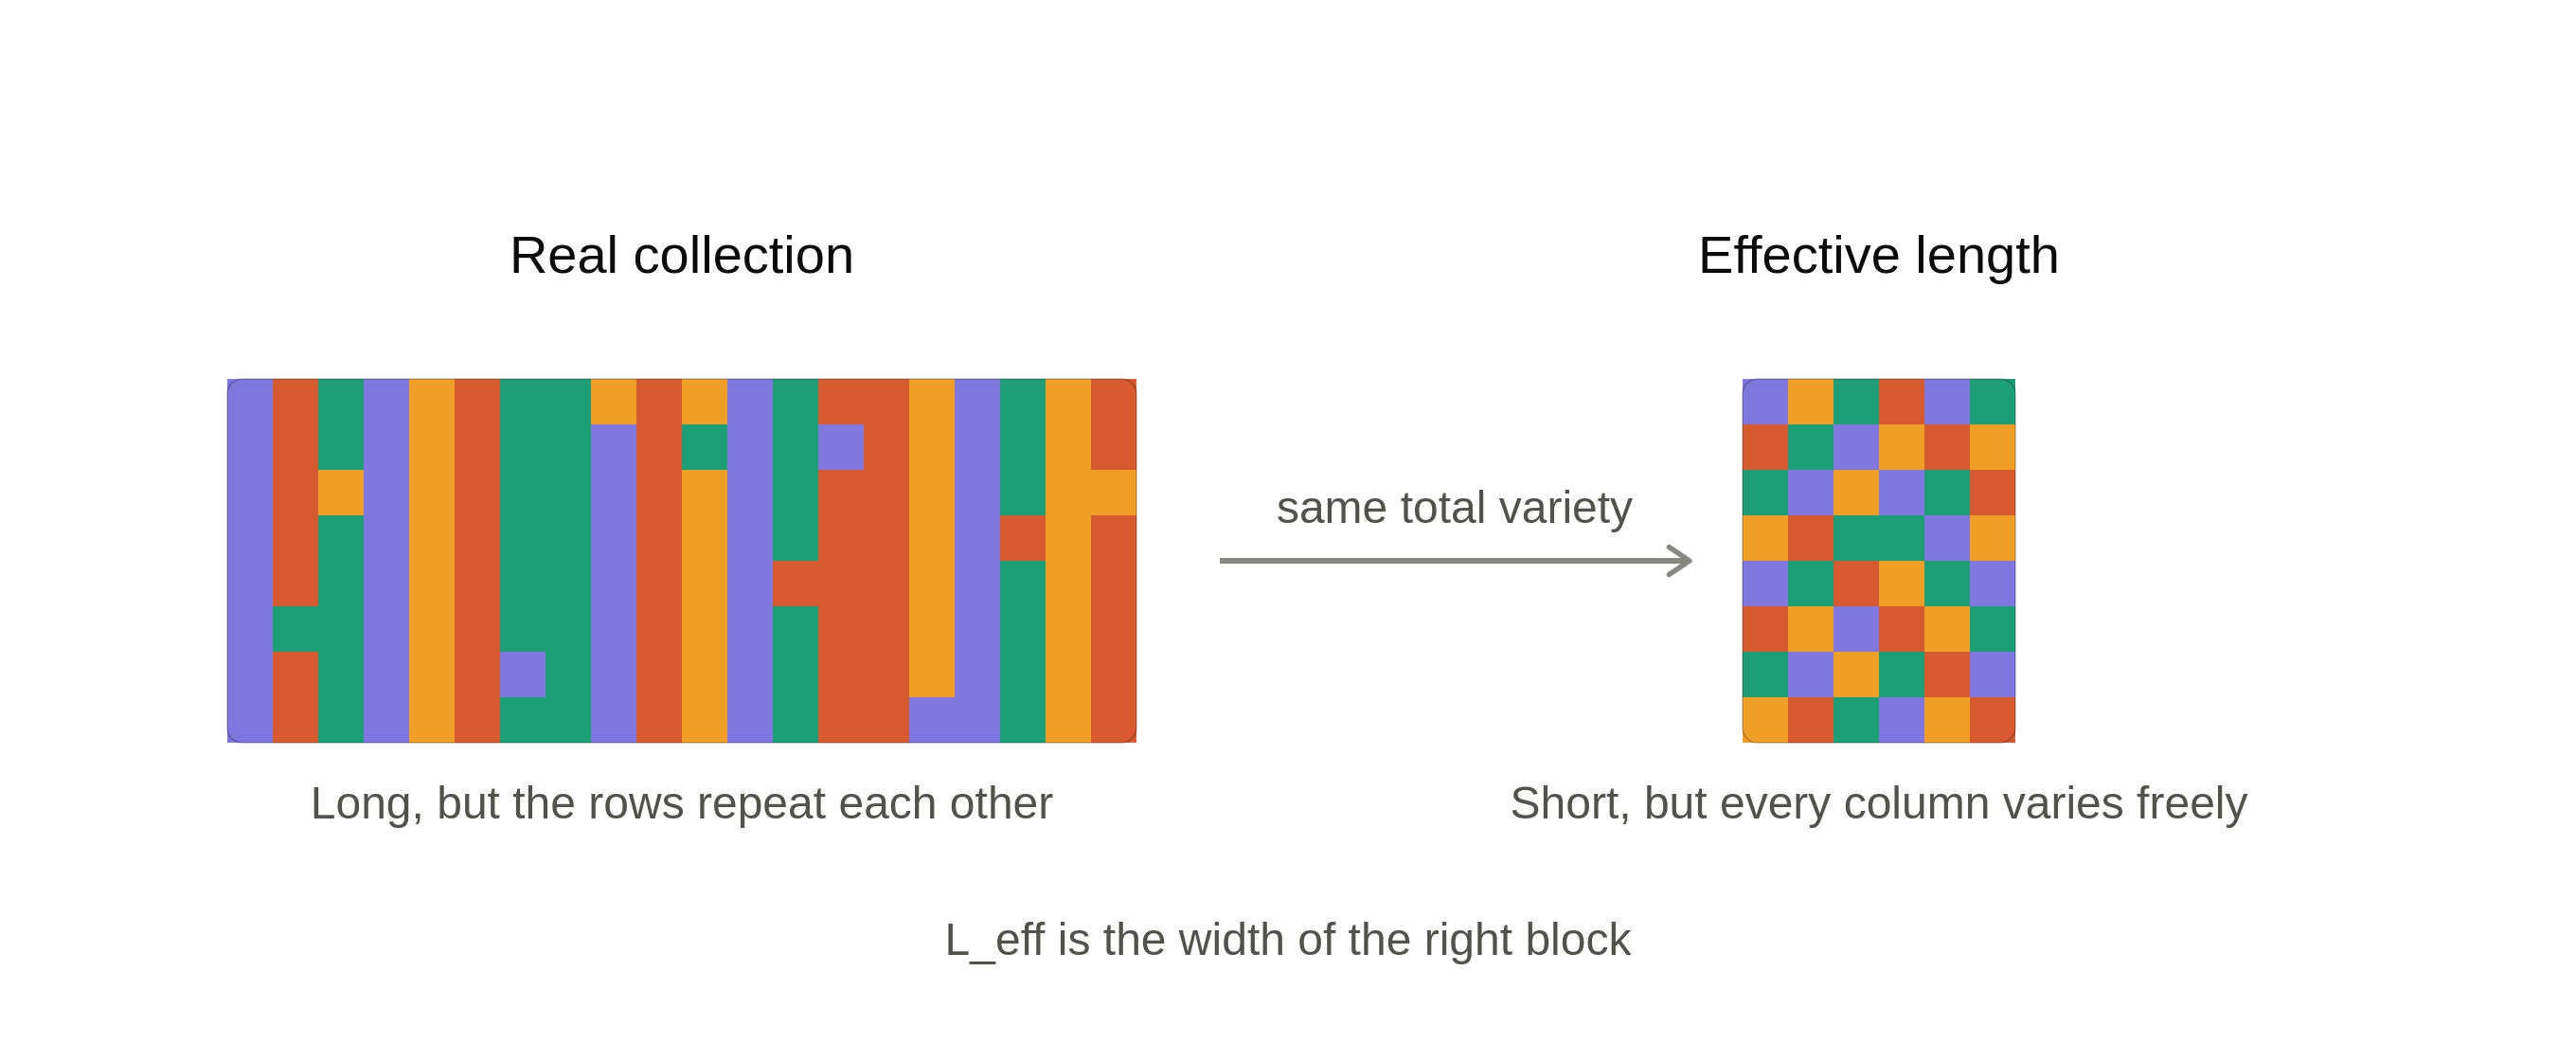
Machine learning has transformed biology, predicting protein structures, uncovering evolutionary rules, and designing new RNA and protein sequences. Almost every such method learns from large collections of related sequences, and the field largely assumes that more data means better models. But more is not always richer. A collection of thousands of sequences may hold far fewer independent evolutionary signals, because so many entries are near-copies shaped by shared ancestry or by designs that scarcely depart from a single template. We rarely know how much real information a dataset carries, let alone how to measure it. Here I introduce the effective length Leff, a simple measure of the genuinely independent information in a sequence collection. It reveals that natural RNA and protein families are far more constrained than their size suggests, anticipates how reliably their structures can be predicted, and distinguishes new sequence libraries that add real information from those that merely repeat what we already know. https://github.com/vaiteaopuu/effective_length